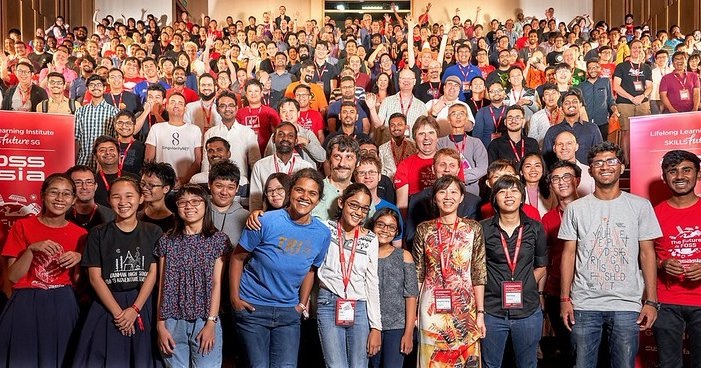
OpenTechSummit India 2026
Meet OpenEverest at OpenTechSummit India 2026
Two talks on running LLMs on Kubernetes and an OpenEverest project table — find us at OpenTechSummit India in Mumbai on Thursday, November 5.
Visit event websiteWhere to find us
- Project table
- Thursday, November 5 · Exhibition area
- Talk
- Prefill, Decode, and Despair — 1:15–1:30 PM IST · Main Stage
- Lightning talk
- What Actually Happens When You Send an LLM Request to Kubernetes? — 4:05–4:10 PM IST · Main Stage
- Venue
- Jio World Centre, G Block, Bandra Kurla Complex (BKC), Mumbai
Who you'll meet
Sergey is a product leader focused on delivering robust open-source solutions. He leads the OpenEverest platform and is a passionate advocate for running data workloads on Kubernetes.
Atharva is a backend engineer and open source contributor to OpenEverest. He enjoys digging into how things work under the hood and writing about it.
OpenEverest at OpenTechSummit India
OpenTechSummit India is a one-day open technology and community event organized by FOSSASIA as part of Devcon 8 at the Jio World Centre in Mumbai. OpenEverest is there with two talks on serving LLMs on Kubernetes and a project table in the exhibition area.
Our talks
Prefill, Decode, and Despair: Disaggregated LLM Serving Made Boring
Sergey Pronin · Thursday, November 5 · 1:15–1:30 PM IST · Main Stage
KServe can serve large language models on Kubernetes — but past “hello world,” it gets sharp. Disaggregated prefill/decode, four kinds of parallelism, autoscaling that behaves differently under KEDA versus HPA, and gateway wiring where one wrong setting silently breaks routing. Sergey shows how OpenEverest’s KServe provider hides all of that behind a single, technology-agnostic Instance resource: ten lines of YAML for an OpenAI-compatible endpoint, and the real traps it saves you from along the way.
What Actually Happens When You Send an LLM Request to Kubernetes?
Atharva Mhaske · Thursday, November 5 · 4:05–4:10 PM IST · Main Stage
A chat completion is rarely one Pod. It crosses a Service, a gateway, a model proxy, a serving controller that may scale from zero, and a model server that streams tokens back — each hop with its own failure mode. Atharva maps that path end to end, using OpenEverest as a concrete case: an Instance CR declares intent, a provider creates a KubeAI Model, and status writes the phase and endpoint back.
Visit the OpenEverest project table
OpenEverest is an open source project to manage databases, storage, and LLMs on Kubernetes, governed by the CNCF. Stop by the OpenEverest table to:
- See how OpenEverest runs LLMs alongside databases with the same Instance-based API.
- Talk databases on Kubernetes — providers, plugins, and what it takes to build your own DBaaS.
- Get involved — learn how to contribute and where newcomers can start.
Bring your questions — and your production war stories.
Not at OpenTechSummit but want to connect?
- Star the project on GitHub
- Join the conversation on our community channels
- Browse other upcoming events
