How an AI Agent Shipped a ClickHouse Provider for OpenEverest
A field report on building a ClickHouse provider for OpenEverest — how little we actually had to build, and how far an AI agent could carry it because the abstraction did the hard part.
Latest news and articles from the OpenEverest project
A field report on building a ClickHouse provider for OpenEverest — how little we actually had to build, and how far an AI agent could carry it because the abstraction did the hard part.
OpenEverest was present at KubeCon + CloudNativeCon India 2026, held in Mumbai on June 18–19.
Learn how to deploy RustFS as a self-hosted S3-compatible object storage service and integrate it with OpenEverest for automated PostgreSQL backups. This step-by-step guide covers deployment, bucket creation, S3 configuration, backup scheduling, and restore validation on a Kubernetes cluster.
Meet Atharva Mhaske — a pre-final year engineering student at Pune University who went down a databases rabbit hole in Go and came out contributing to OpenEverest.
OpenEverest v2 Developer Preview is here. A modular architecture with a Provider SDK, Generic Plugins, and a streamlined UX — all designed so developers can integrate new database technologies in days, not months.
GKE is the go-to Kubernetes option for a lot of teams. This walkthrough covers installing OpenEverest on a standard GKE cluster - the commands, config, and gotchas - so you can get a database running on Google Cloud.
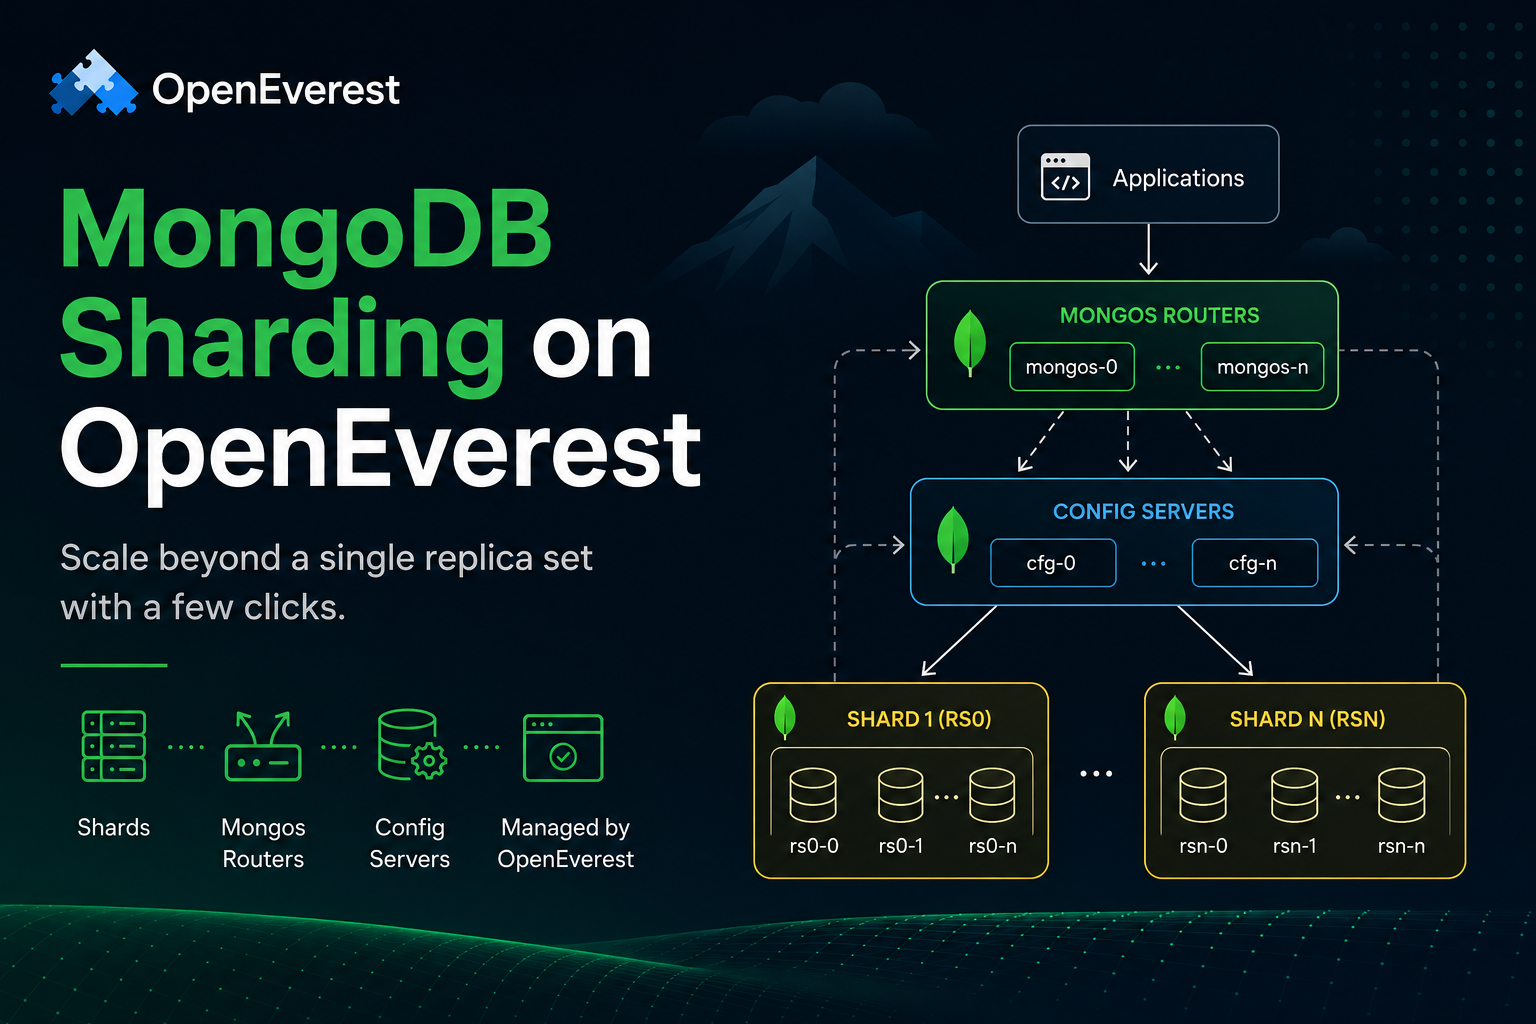
Walk through enabling MongoDB sharding in the OpenEverest UI and verify the config servers, mongos routers, and shard pods created in your namespace.
OpenEverest 1.15 adds native ARM64 support across all components. This post covers supported workloads, current limitations and the other changes included in the 1.15 release series.
Run OpenEverest locally with kind and everestctl to create and manage PostgreSQL on Kubernetes. A practical step-by-step guide covering setup, database creation, and resource debugging on a laptop.
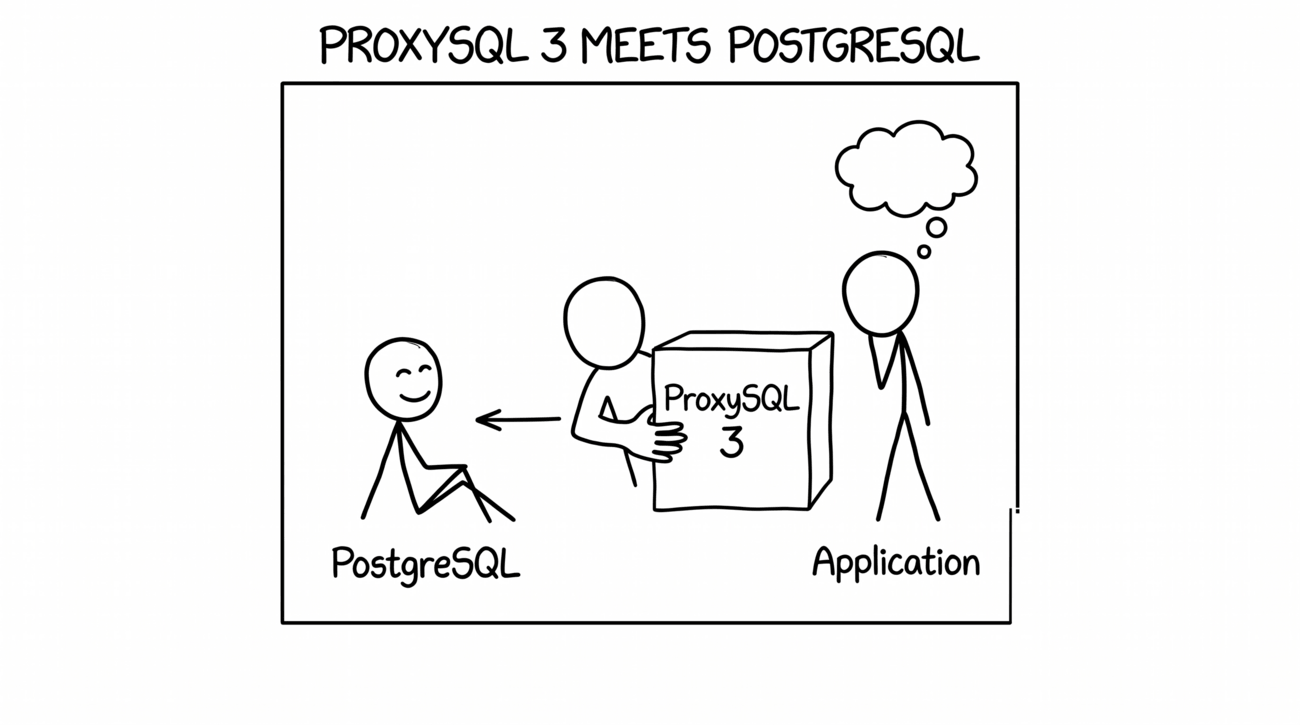
ProxySQL 3 added PostgreSQL support. Let's see how hard it is to deploy it in front of a Patroni-managed PostgreSQL cluster on Kubernetes and get read/write splitting working.